A Check That Could Never Be True
Nanocoder tested for a string prefix its own code never emits, so a flag was permanently false. Fixing the string alone would still have left it broken.
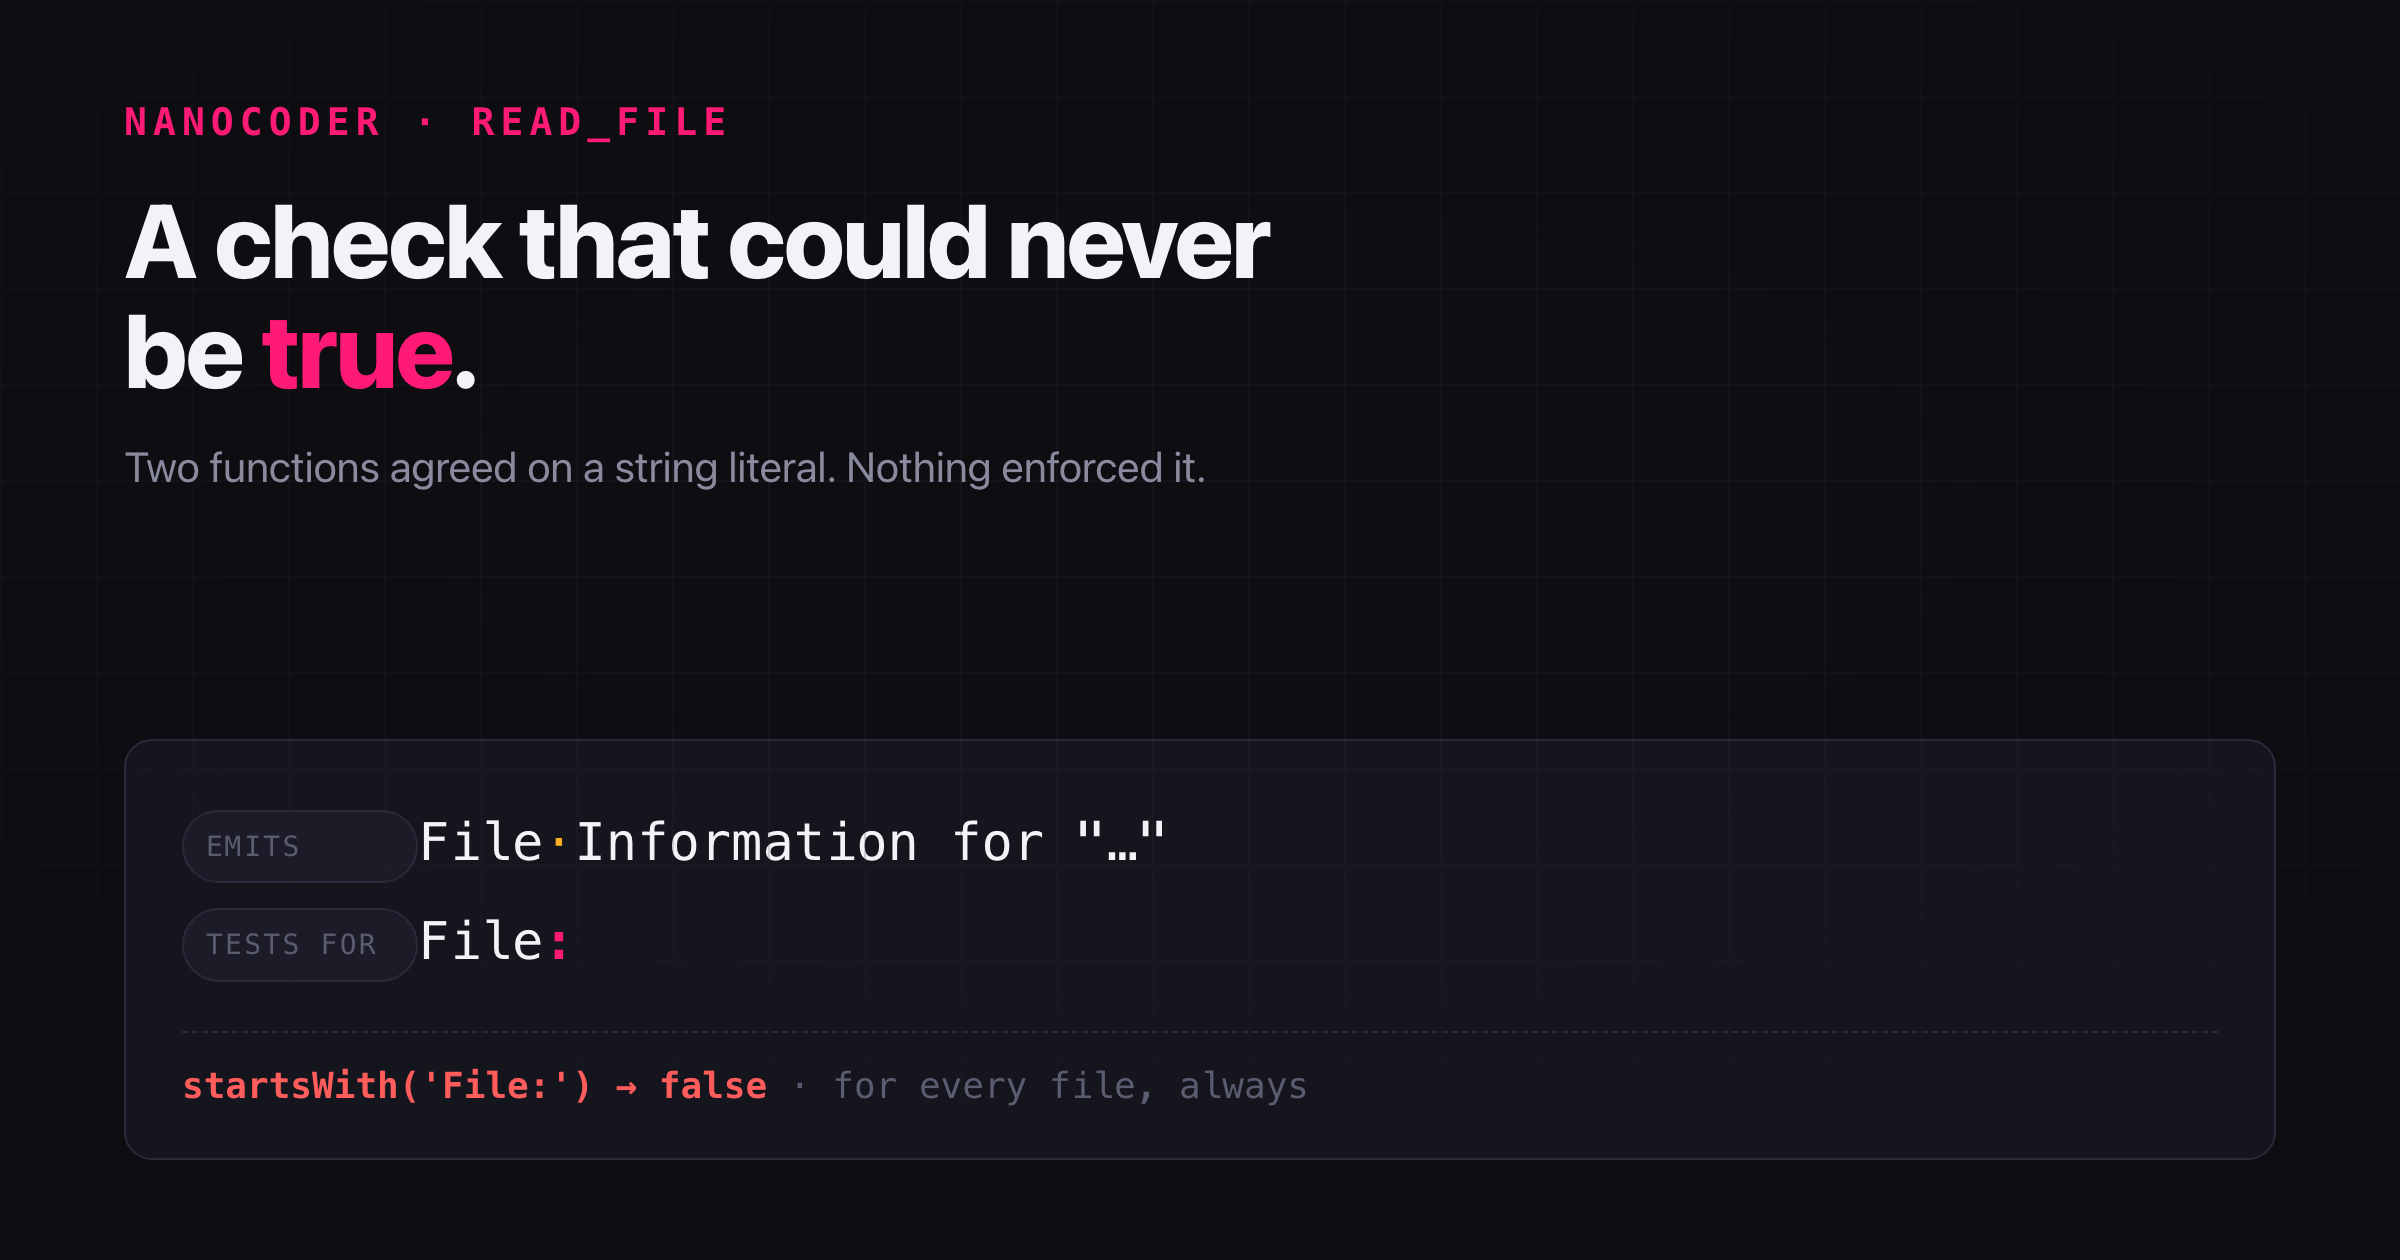
Nanocoder's read_file tool can return just a file's metadata instead of its contents. When it does, the UI is supposed to say "(metadata only)" and show a metadata layout.
It never did. The check that decides was written like this:
const isMetadataOnly =
  (result?.startsWith('File:') ?? false) &&
  !args.start_line &&
  !args.end_line &&
  totalLines > FILE_READ_PREVIEW_THRESHOLD_LINES;
And the metadata branch emits this:
let output = `File Information for "${args.path}"\n`;"File Information for ..." does not start with "File:". The fifth character is a space, not a colon. The test could never return true, in any circumstance, for any file.
The half that's easy to miss
Fixing the string alone would still have left it broken.
Look at the other three conditions. They require that no line range was requested and that the file is over the 1500-line preview threshold. Those describe a completely different response.
read_file returns one of three shapes:
| Shape | Detected by |
|---|---|
| metadata block | isMetadataOnly — the broken one |
| truncated preview | result.includes('[Truncated at line ') ✅ |
| plain content | neither |
The size and line-range conditions belong to the truncated preview — which already has its own correct check on the very next line. They were never relevant to metadata.
And they can't be, because of where the metadata branch sits. It's guarded by if (args.metadata_only) at the top of the function and returns before any line range or file size is looked at. So a metadata read on a 120-line file would have failed the > 1500 threshold even if the prefix had matched.
Two independent reasons the condition could never be true, for two different reasons. Fix one and you still have a bug.
What users actually saw
With the flag stuck false, a metadata-only read rendered as a normal content read:
- no "(metadata only)" marker
- the content-read layout instead of the metadata layout
- a "Tokens:" row that's meant to be hidden for metadata reads
- a token count measured from the metadata block itself rather than from the file — a number that looks right and describes the wrong thing
That last one is the reason a bug like this survives. Nothing crashes. Nothing is empty. There's a plausible number on screen, and it's simply about the wrong text.
The fix
-const isMetadataOnly =
-  (result?.startsWith('File:') ?? false) &&
-  !args.start_line &&
-  !args.end_line &&
-  totalLines > FILE_READ_PREVIEW_THRESHOLD_LINES;
+const isMetadataOnly = args.metadata_only === true;
The request flag is what selects the response shape in the first place. Inferring it back out of the output string was always a guess at something already known for certain.
One thing worth checking after a change like this
Deleting the condition removed the only other use of FILE_READ_PREVIEW_THRESHOLD_LINES in that function. If it had been the last use in the file, the import would have gone unused and the project's knip and lint checks would have failed.
It's still used at line 123, so the import stays. But that's worth thirty seconds of checking whenever you delete a condition — removing code can break a build in a place you never edited.
The PR is Nano-Collective/nanocoder#987.
The general shape
This bug is a string literal being used as a contract between two functions, with nothing enforcing it. One side wrote File Information for, the other read File:, and no type, test, or compiler had any opinion about the disagreement.
Anywhere you see startsWith or includes against a hardcoded prefix, there's a contract like that. It holds right up until someone rewords the message.